◉
Listen
Capture voice through a USB microphone and manage interaction on an ESP32-S3.
 Get in touch
Our long-term goal is a small, expressive AI companion you can talk to in the physical world. Starting with an ESP32-S3 conversation-device prototype, we plan to connect Claude-powered dialogue with a voice, an animated face and responsive hardware.
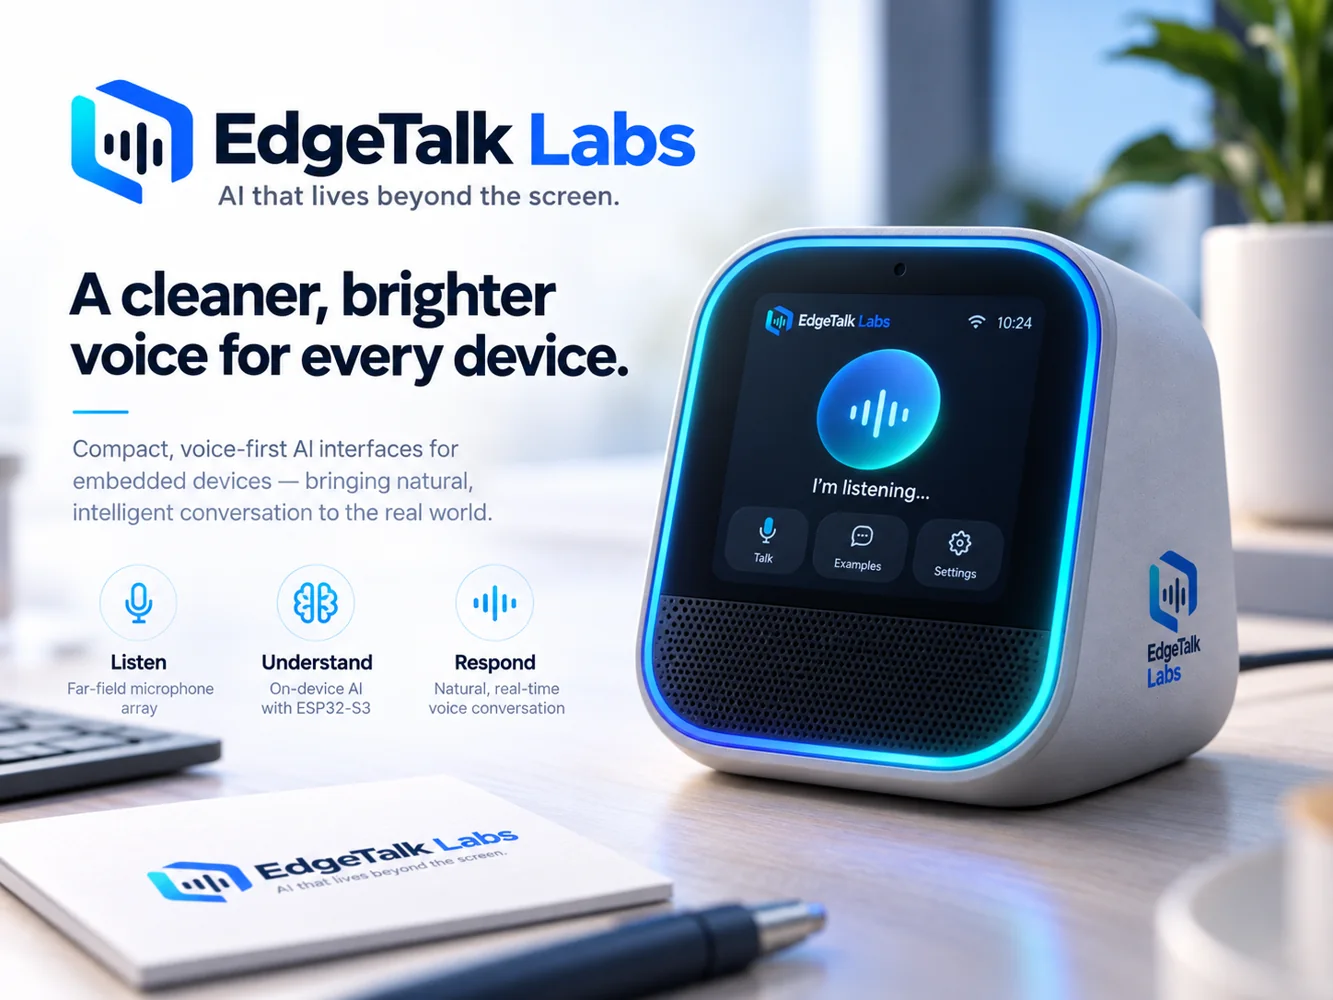
The vision is a characterful physical companion: one that can hold a conversation, express its interaction state on a display, and eventually remember preferences with the user’s permission. The first milestone remains a working conversation loop.
Capture voice through a USB microphone and manage interaction on an ESP32-S3.
Send structured requests over HTTPS to a frontier model API. Claude is the initial target reasoning layer.
Return spoken replies and expressive on-screen feedback. Supported hardware actions can follow once the conversation loop is reliable.
The hardware direction centers on ESP32-S3, audio input and output, and a small display. The next step is to connect this foundation to a Claude-powered backend and evaluate the complete interaction.
Audio input
Display feedback
Wi-Fi connectivity
Earlier independent-study work focused on ESP32 hardware assembly, wiring, soldering, power integration and firmware flashing.
Planned: a backend that sends transcribed requests to Claude and returns conversational replies and structured device commands.
Future: a repeatable demo, measured latency and reliability, then enclosure design and onboarding.
Proposed architecture: the device handles hardware interaction; a backend coordinates speech services, conversational context and model requests.
Integration note: Claude integration is planned and is not yet deployed. Speech recognition and synthesis are separate services. API credentials belong on the backend, rather than in device firmware.
A small physical presence for questions, casual conversation and shared curiosity, with voice and display feedback.
Explore ideas and explain concepts through dialogue. The hardware itself remains a hands-on embedded-systems learning project.
Use an animated face and clear device states to give conversations a physical character. Longer-term personalization is a future goal.
We plan to use Claude to interpret transcribed requests, maintain conversational context and generate structured responses. Device actions will be limited to supported commands. Our evaluation will focus on response quality, latency, reliability and cost per interaction.
EdgeTalk grows out of an earlier “build an intelligent conversation device” independent-study project. The emphasis was hands-on embedded learning: assembling hardware, integrating power and loading firmware.
The independent-study work explored ESP32-based conversation hardware and the Xiaozhi open-source project. It covered wiring, soldering, power integration and firmware flashing.
This is the project's learning foundation, rather than an original claim over the open-source firmware.
Build a backend that coordinates transcription, Claude requests and speech output. Show a complete voice-to-response interaction on development hardware.
Claude integration is planned. No production deployment or performance figures are claimed.
Record response latency, successful interactions, connection failures and API cost. Use the findings to guide device-state feedback, error recovery and enclosure design.
These are proposed evaluation criteria; results will be published after testing.
Reliable power and connections • clear listening and response states • recoverable network errors • backend-managed credentials • bounded device actions
EdgeTalk Labs is an independent, founder-led hardware project in Taiwan, exploring voice interfaces for embedded devices. The work connects an earlier independent-study effort with a new cloud reasoning integration plan.
The project is at the personal-prototype stage. Its long-term goal is an expressive physical AI companion; the immediate goal is a repeatable voice-to-response demonstration on development hardware. EdgeTalk Labs is a working project name and is not currently an incorporated company.
For technical questions, feedback or collaboration, contact the project directly.
hello@fatevault.org